Works with the AI Agents you already use
 Claude Code
 Cursor
 Codex CLI
 Muse
 Dots+21 moreClaude CodeCursorCodex CLIMuseDots
 Manus
 Grok
 Grok Bot+18 agents
RAG Diagnostics
Separate query, retrieval and generation failures with evidence, then fix the layer that is actually broken.
$15

RAG Diagnostics
Example session with this skill installed
"It hallucinates" is a symptom with three possible causes, and teams usually fix the wrong one: they swap the model when the chunking is broken, or rewrite prompts when the index is missing the answer.
RAG Diagnostics separates the layers with evidence and tells you which one is failing, how often, and what to change first: query failure, retrieval failure, or generation failure.
What it does
- Labels real queries by whether the gold answer was retrieved and whether the answer used it, giving a 2x2 that splits failures by layer.
- Distinguishes query failure from retrieval failure by rephrasing the query: if the rewrite finds the gold chunk, the index was fine.
- Separates unsupported answers from wrong ones, which is the difference between a grounding problem and a knowledge problem.
- Finds the pattern inside each class — tables, new documents, follow-ups, comparative questions — because "recall is 0.62" is not actionable.
- Prescribes one fix per class with expected effect, then turns the failures into a regression set.
What you get
A verdict (X% retrieval, Y% generation, Z% query), findings with query IDs and chunk scores, a ranked fix table, and the regression set that keeps the fix from being undone by the next prompt tweak.
Honest scope
It needs retrieval logs and, ideally, gold answers. Without them it says the analysis is qualitative rather than inventing recall numbers. It does not re-index your corpus or benchmark vector databases.
No dependencies. Works with the logs you already have.
- Read your context and instructions
- Compiled the rag diagnostics
RAG diagnostics: docs assistant
Verdict
61% of bad answers are retrieval, 24% generation, 15% query.
The highest-impact fix is semantic chunking for tables, followed by hybrid search for IDs.
Sample
120 queries, support logs, last 30 days. Gold answers available for 98.
Layer split
| Layer | Share | Evidence |
|---|---|---|
| Retrieval | 61% | Gold chunk absent from the top 10 in 60 cases |
| Generation | 24% | Gold chunk present, answer contradicts it |
| Query | 15% | Follow-up questions with no conversation context |
Findings
R1 — Tables are split across chunks
Evidence: 22 failures, all on pricing and spec tables; chunk boundaries fall mid-row.
Fix: semantic chunking with 15% overlap, tables kept whole. Expected: 22 failures recovered.
Verify: re-run the 98 queries, compare gold-present rate.
R2 — Documents added after the last reindex are invisible
Evidence: recall 0.31 on documents newer than 14 days.
Fix: nightly reindex. Expected: 11 failures recovered.
G1 — Comparative answers ignore sources
Evidence: 14 cases where the right chunk was retrieved and the model answered from memory.
Fix: source-before-question ordering plus citation requirement and an abstain path.
Fix order
| # | Fix | Failures | Effort |
|---|---|---|---|
| 1 | Semantic chunking for tables | 22 | M |
| 2 | Hybrid BM25 for IDs and exact terms | 18 | L |
| 3 | Citation-required prompt with abstain | 14 | L |
| 4 | Nightly reindex | 11 | L |
| 5 | Context-aware query rewriting | 9 | M |
Regression set
The 98 labelled queries committed as the baseline; every change re-runs it.
Connects securely to your tools. The creator never sees your data.
About this skill
RAG diagnostics: separate query, retrieval and generation failures with evidence, then fix the layer that is actually broken.
Use this skill when:
- RAG answers are wrong
- the assistant hallucinates
- retrieval quality is unclear
- work out why documents are missed
Who it's for: Teams whose RAG assistant gives bad answers.
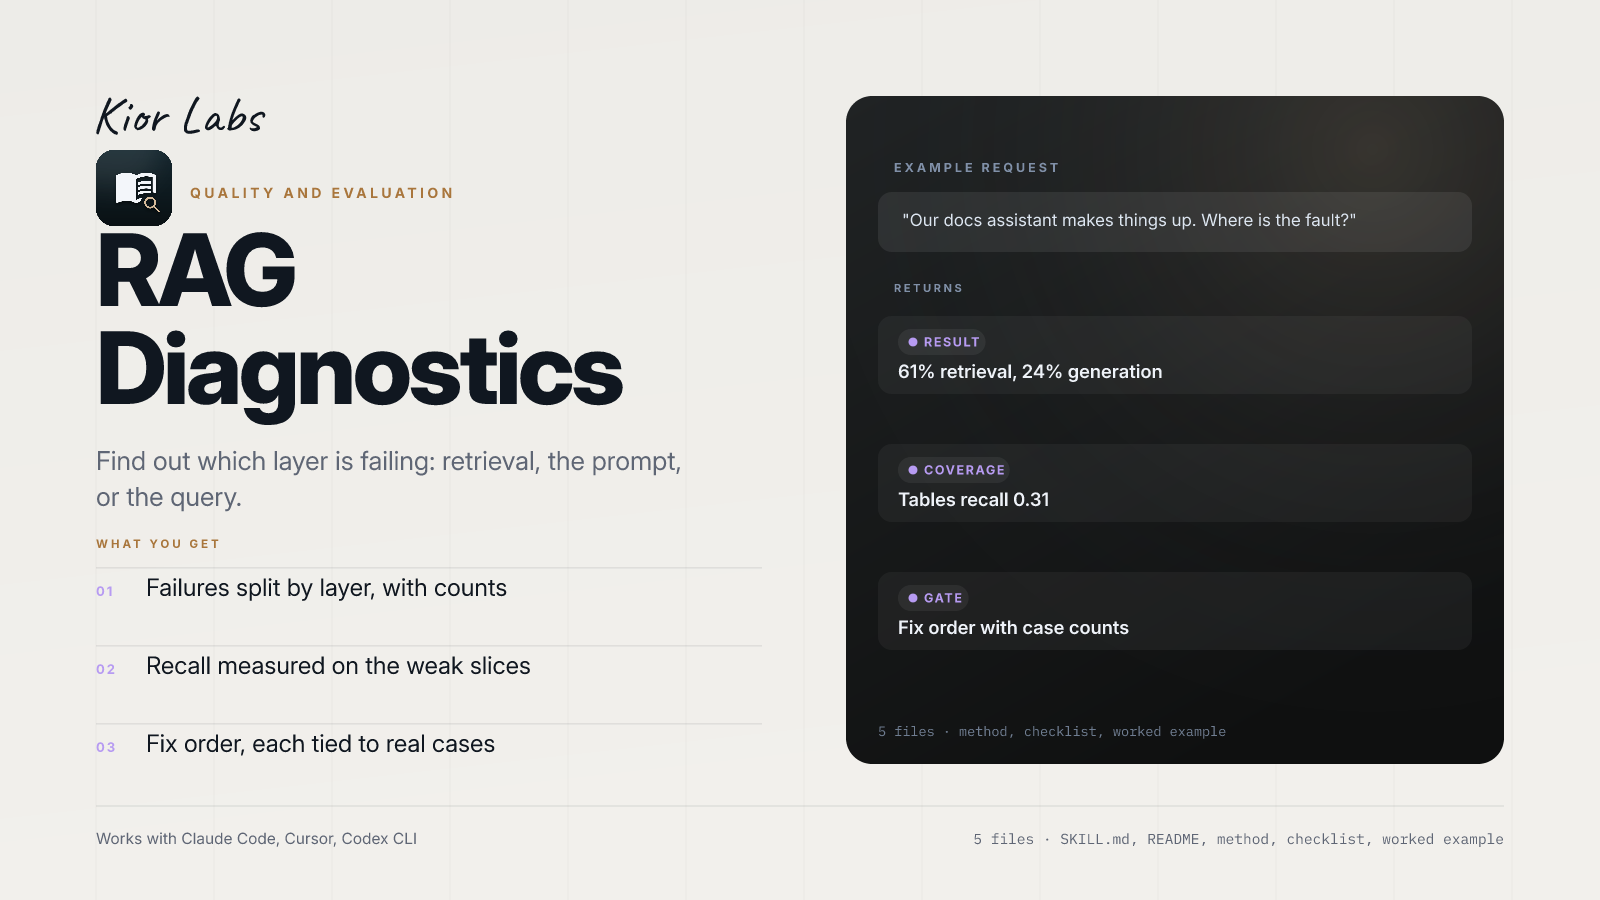
Example request
Our docs assistant makes things up. Where is the fault?
What the example returns
- 61% retrieval, 24% generation
- Tables recall 0.31
- Fix order with case counts
In the package: five files — SKILL.md with the trigger and workflow, README.md, references/METHOD.md (the full method), references/CHECKLIST.md (the pass/fail gate) and examples/EXAMPLE.md (a worked run you can copy).
Works with Claude Code, Cursor, Codex CLI and any agent that reads SKILL.md. Plain markdown: no API key, no account, no network access.
Requires retrieval logs (chunk IDs and scores) to function. Cannot assess content gaps if the answer is entirely missing from the corpus. Does not perform re-indexing or code execution.
How to use
- 1
Connect your agent to the Agensi MCP
Copy the prompt and paste it into Claude, ChatGPT, Cursor or any agent that supports MCP. It sets up the connection for you. Manual setup
- 2
Sign in to Agensi
Your agent shows a sign-in link. Sign in and click Allow.
- 3
Ask for what you need
Your agent loads this skill and uses it on your task. It always asks before any payment.
Reviews
No reviews yet
Be one of the first to try it. Every listed skill goes through the trust checks below.
Security scanned
Checked by our 8-point scan before listing
Fresh listing
Recently published to Agensi
Money-back guarantee
Doesn't do what its page promises? You get your money back.
Trust & safety
Security scan
Security scan passed 2 days ago