Works with the AI Agents you already use
 Claude Code
 Cursor
 Codex CLI
 Muse
 Dots+21 moreClaude CodeCursorCodex CLIMuseDots
 Manus
 Grok
 Grok Bot+18 agents
Eval Dataset Curator
Build a gold eval set from production data: stratified, deduplicated, labelled and versioned.
$15

Eval Dataset Curator
Example session with this skill installed
Our evals are 40 cases we wrote by hand and they all pass while production fails. Help me build a real gold set from 8,000 production runs.
- Read your context and instructions
- Compiled the eval dataset curator
Worked example — illustrative data.
Eval dataset plan: support agent
Verdict
A 240-case stratified set from 14 days of traffic, four-field schema, 86% raw agreement (kappa 0.71), covering 12 intents and 3 difficulty bands. Gaps: voice, non-English, enterprise tier.
Sampling plan
| Stratum | Population | Sample |
|---|---|---|
| Order status | 3,100 | 48 |
| Refunds | 1,900 | 48 |
| Returns policy | 1,200 | 36 |
| Address change | 700 | 24 |
| Escalation | 600 | 24 |
| Other (7 intents) | 500 | 60 |
Stratified by difficulty (short/long/tool-heavy) and outcome (pass/fail), across 14 days.
Label schema
- Verdict: pass / fail / partial, with one-line definitions.
- Failure class: wrong fact, missing action, unsafe, formatting, tone.
- Difficulty: easy / medium / hard, defined by domain knowledge needed.
- Confidence: high / low; low goes to adjudication.
Labelling guide
Three worked examples per verdict, including the borderline case: a correct answer that failed to confirm a refund amount.
Deduplication
Token-overlap above 0.8 removed 61 cases. Kept the version with the richest metadata.
Leakage checks
- Answer in input: 4 cases removed.
- Mock-dependent: 9 flagged, kept with mocks pinned.
- Time-dependent: 12 excluded (prices change weekly).
Maintenance
Additions need a second label; removals need a reason. Version as support-gold-v1, v2.
What this set cannot tell you
Nothing about voice, non-English, or enterprise-specific tools.
Connects securely to your tools. The creator never sees your data.
About this skill
Eval dataset curation from production traffic: dedupe, stratify, label, and document coverage so the scores mean something.
Use this skill when:
- build an eval set
- measure quality without gold data
- evals do not reflect production
- label and stratify test cases
Who it's for: AI teams whose evals do not match reality.
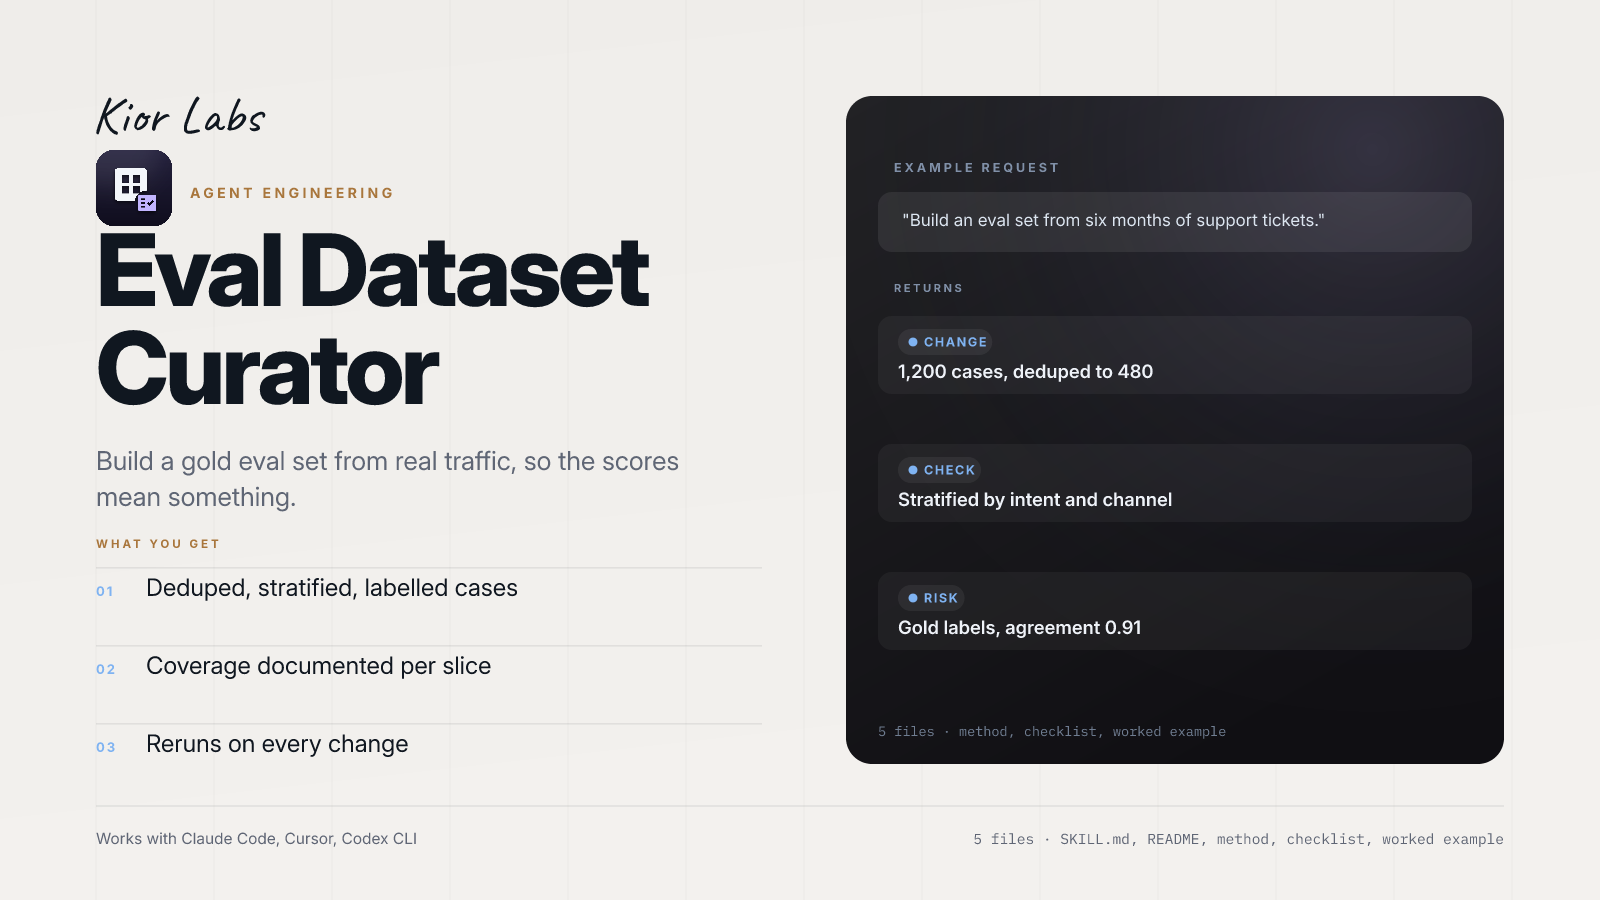
Example request
Build an eval set from six months of support tickets.
What the example returns
- 1,200 cases, deduped to 480
- Stratified by intent and channel
- Gold labels, agreement 0.91
In the package: five files — SKILL.md with the trigger and workflow, README.md, references/METHOD.md (the full method), references/CHECKLIST.md (the pass/fail gate) and examples/EXAMPLE.md (a worked run you can copy).
Works with Claude Code, Cursor, Codex CLI and any agent that reads SKILL.md. Plain markdown: no API key, no account, no network access.
Does not provide an eval harness or execution engine. Requires human domain experts for ground truth labeling. Small datasets (under 150 cases) may lack statistical significance.
How to use
- 1
Connect your agent to the Agensi MCP
Copy the prompt and paste it into Claude, ChatGPT, Cursor or any agent that supports MCP. It sets up the connection for you. Manual setup
- 2
Sign in to Agensi
Your agent shows a sign-in link. Sign in and click Allow.
- 3
Ask for what you need
Your agent loads this skill and uses it on your task. It always asks before any payment.
Reviews
No reviews yet
Be one of the first to try it. Every listed skill goes through the trust checks below.
Security scanned
Checked by our 8-point scan before listing
Fresh listing
Recently published to Agensi
Money-back guarantee
Doesn't do what its page promises? You get your money back.
Trust & safety
Security scan
Security scan passed 2 days ago